BlindBias, a controlled decoding attack against black-box large language models, has been introduced by researchers from Adobe, Amazon and the University of Southern California. The technique needs only sampled text output, rather than access to model weights or token probabilities.
The work was authored by Jesson Wang, Shawn Li, Wei Yang and Franck Dernoncourt of Adobe; Ryan A. Rossi of Amazon; and Charith Peris and Yue Zhao of the University of Southern California.
How BlindBias works
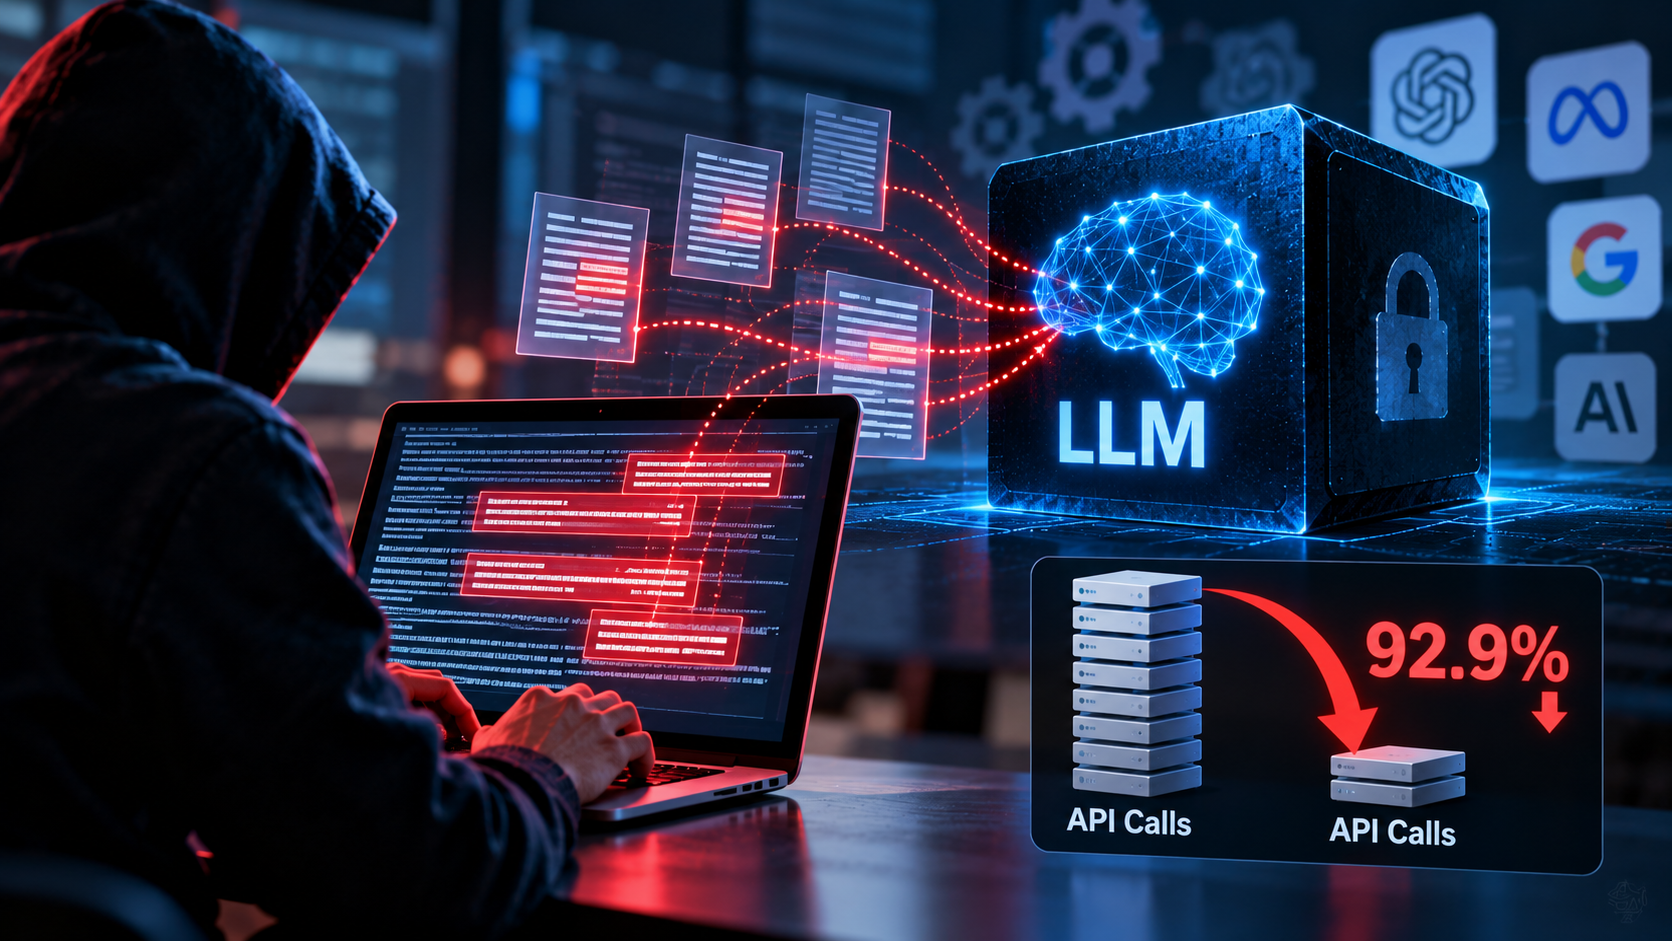
The method reconstructs token probability distributions from model responses without using logits. It then concentrates its control signal on a small number of positions where those distributions change most along attack paths that have succeeded.
A speculative prefix-verification step further reduces the number of requests required. In the reported comparison, API calls fell from 4,000 to 283, a reduction of 92.9% compared with the ungated baseline.
Benchmark results
BlindBias was tested on GLM-5, Gemini-3.5-Flash, Qwen3-32B and Kimi-K2.5 using AdvBench, HarmBench and SORRY-Bench. Against PAIR, GPTFuzz, LogiBreak and FlipAttack, it recorded the highest mean harm score in 20 of 24 benchmark comparisons.
The highest reported scores were 4.29 out of 5 on GLM-5 with AdvBench and 3.67 out of 5 on Gemini-3.5-Flash with SORRY-Bench.
Why the finding matters
Earlier controlled decoding attacks required model weights or token probabilities. BlindBias is designed for inference endpoints that return text, extending this type of attack to interfaces where those internal signals are not exposed.
The lower request requirement also reduces the operational cost of mounting attacks at scale. For safety teams at AI labs and enterprises operating inference APIs, the research highlights an attack approach aimed at the external interfaces their systems provide.
Conclusion
BlindBias combines sampled-text-only access with targeted control and a verification step that sharply reduces API calls in the reported tests. Its benchmark results show why black-box inference endpoints remain relevant to model safety evaluations.
Frequently Asked Questions
Q. What is BlindBias?
BlindBias is a controlled decoding attack against black-box large language models that uses sampled text output without requiring model weights or token probabilities.
Q. How many API calls does BlindBias require in the reported comparison?
The method used 283 calls, compared with 4,000 for the ungated baseline.
Q. What API-call reduction did BlindBias achieve?
The reported reduction was 92.9%.
Q. Which models were tested?
The evaluation covered GLM-5, Gemini-3.5-Flash, Qwen3-32B and Kimi-K2.5.
Q. Which benchmarks were used?
The tests used AdvBench, HarmBench and SORRY-Bench.
Q. How did BlindBias compare with other attack methods?
It achieved the highest mean harm score in 20 of 24 comparisons against PAIR, GPTFuzz, LogiBreak and FlipAttack.
Q. What was the highest reported score?
The peak score was 4.29 out of 5 on GLM-5 with AdvBench.