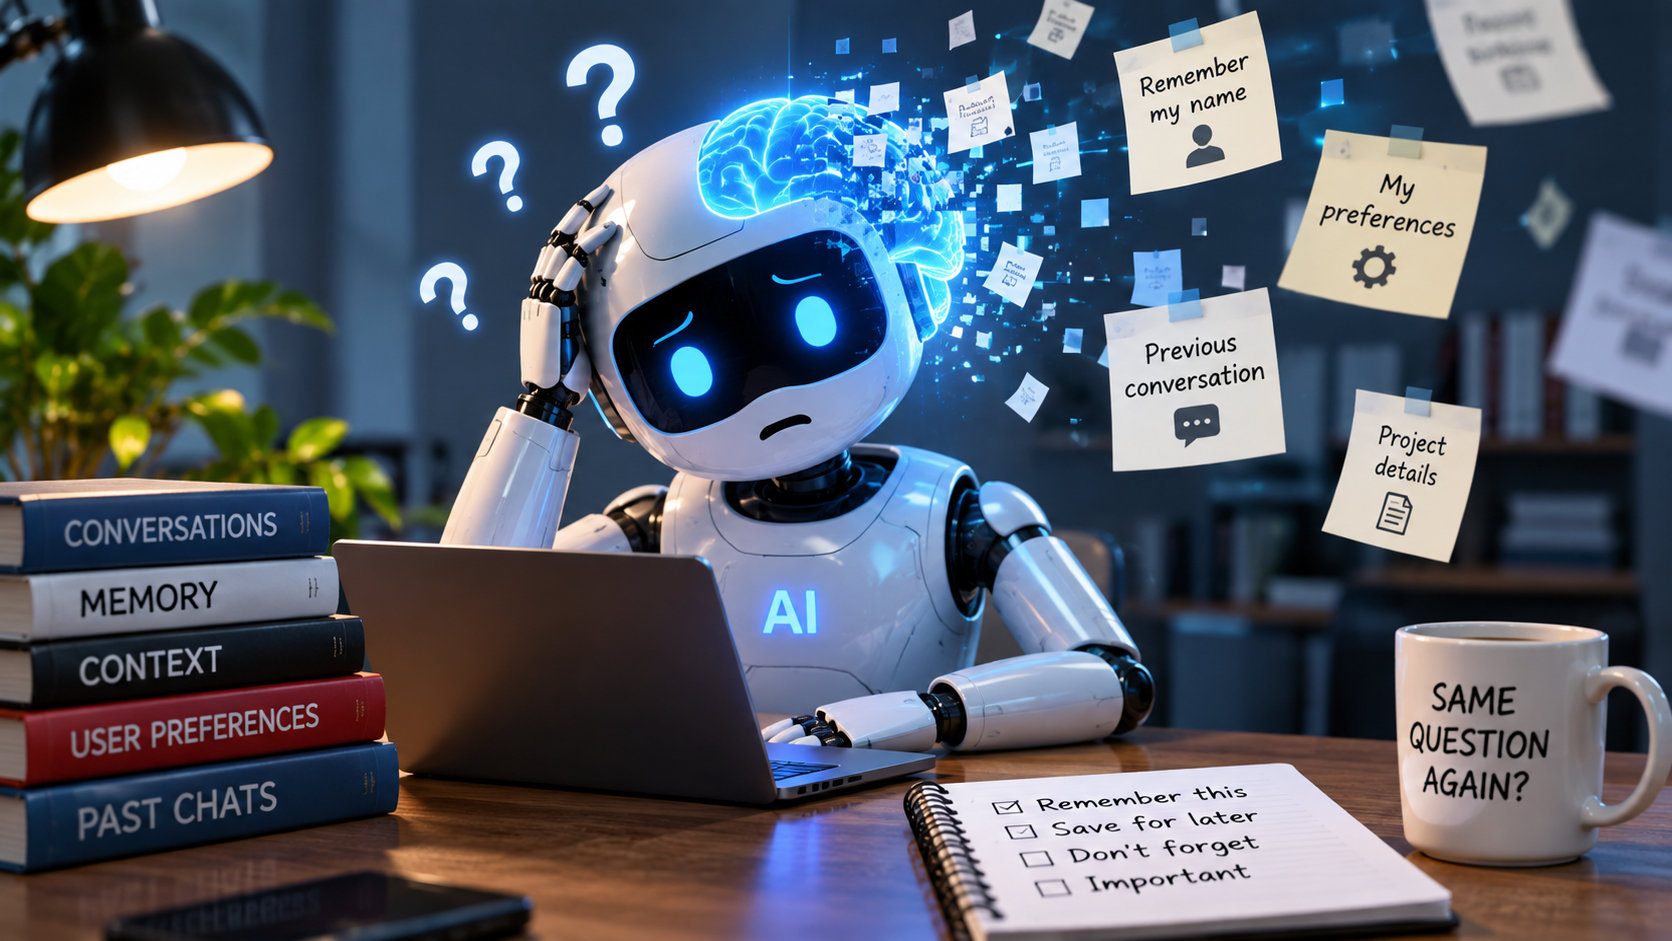
AI systems can write, code, answer questions and carry information between conversations. Yet an assistant may still lose track of an earlier instruction, preference or detail. This behaviour is often called “AI amnesia”, but it is not human-style memory loss. Several different technical problems can produce the same impression.
The distinction matters because AI tools are increasingly being used for long-running tasks. An assistant handling documents, emails, databases and earlier conversations must not only retain information. It must also identify what is relevant, retrieve it at the right time and distinguish current instructions from older ones.
Context is not the same as memory
A language model produces an answer from the information available when a request is processed. Previous messages may be included in that input, but the model does not independently recall an earlier conversation in the way a person recalls a personal experience. The application must provide the relevant information again.
That makes AI “memory” a combination of the model's current context and additional systems around it. Those systems can store user information, create summaries, use databases or retrieve details from earlier interactions before adding them to a new conversation.
OpenAI describes ChatGPT memory as a way to carry useful information and preferences from earlier conversations into later ones. Its stated aims include carrying forward relevant context, following user preferences and updating information as circumstances change. The model receives that retrieved material as part of the context used to produce a response.
Why long chats can cause apparent forgetting
Every AI model can process only a certain amount of information at one time. The input may contain the current request, earlier messages, instructions, documents and other material. As a conversation grows, the system has more information to process and the model may not use every part equally well.
Experiments involving Claude Sonnet and GPT-5 found that responses could become less consistent as more material was added to the context. The phenomenon has been described as “context rot”: performance can deteriorate before the model reaches its stated context limit.
The issue can be especially visible when an important detail is surrounded by unrelated information. In one experiment, information placed in the middle of a large context was more likely to be missed or mixed with details from elsewhere in the input.
This does not necessarily mean that the earlier information was erased. It may still be present, but receive insufficient attention when the model generates its answer. Similar problems can lead to missed information, mixed details between documents and inconsistent summaries when a model works with a large amount of context.
Training creates a different kind of forgetting
In machine learning, “catastrophic forgetting” refers to a model losing some ability on an earlier task after learning new information or being fine-tuned for another task. IBM describes this as new training interfering with knowledge associated with previous tasks.
The change is linked to the model's internal parameters. As those parameters are adjusted, performance on an older task can decline. This is different from an assistant failing to use something mentioned in yesterday's chat. The first problem concerns training and learned capabilities; the second may involve context, storage or retrieval.
Models are regularly updated, fine-tuned and improved. Changes to their weights can affect how they respond to information they previously handled differently. Techniques including regularisation, rehearsal and architectural approaches are used to reduce the risk of losing earlier capabilities, but an update can still make a system appear to have forgotten something.
Can an AI be made to forget information?
Machine unlearning examines whether selected information can be removed from a trained model without retraining the entire system. The area is relevant to privacy, copyright and information that has become outdated.
“Selective amnesia” describes an approach in which particular information is removed while broader capabilities are retained. Research has included attempts to make a model forget information related to the Harry Potter books while preserving its wider abilities.
The process is not equivalent to deleting a file. Information in a trained model is represented through patterns and relationships in its parameters, so removing one piece of knowledge may affect other capabilities. Researchers must also determine whether the information has genuinely been removed. Material that appears to be gone may sometimes be recovered through carefully designed prompts.
Why the issue matters for AI assistants
For a casual chatbot exchange, losing a detail may be inconvenient. The consequences can be more serious when an assistant works on a long-running project, manages business information or operates as an agent. In those settings, failing to retain an important instruction or using outdated information can affect the quality of the work.
The wider challenge is therefore not simply to give AI systems more storage. They need to remember useful information, retrieve it when needed, update it when circumstances change and avoid confusing older information with newer information.
Conclusion
“AI amnesia” is an umbrella term for several different failures involving context, memory systems, retrieval, training and model updates. Separating these causes is essential to understanding what an AI assistant has actually retained, what it can access and why its response may change.
Frequently Asked Questions
Q. What is AI amnesia?
AI amnesia is a general term for situations in which an AI system appears to forget an earlier detail, instruction or preference. It can result from context limits, retrieval problems, model updates or training-related changes.
Q. Does AI remember like a human?
No. A language model generates a response from the information available during processing. Applications can add stored information, summaries or retrieved details to the model's current context.
Q. Why do AI models struggle with long conversations?
As more messages and documents enter the context, the model may use some information less effectively. Important details can be missed or mixed with unrelated material even before the stated context limit is reached.
Q. What is catastrophic forgetting?
Catastrophic forgetting is a machine-learning problem in which new training or fine-tuning reduces a model's ability to perform an earlier task. It differs from failing to retrieve a detail from a previous conversation.
Q. What is machine unlearning?
Machine unlearning studies whether selected information can be removed from a trained model without retraining the entire system. Proving that information has been completely removed remains difficult.
Q. Why do model updates change an AI's behaviour?
Updates can alter a model's weights and learned behaviour. As a result, the system may respond differently to information or tasks it handled in an earlier version.